
note: this post is co-written with Lennart Otte, whose paper inspired much of its thinking. his sections are Capitalized Properly and italic. i’ll try to be clear about who’s talking when. so anyways, here goes:
what if the we could come up with alien proteins?
not an existing drug repurposed. not a new combination of things we already have. i mean a protein nature never made, but one that’s physically buildable1 the moment we work out the gene edits to make it. an alien protein, if you will.
i read this really sick paper recently. i know what i said, i know. but this one deserved being written. Lennart wrote it. he’s onto something here. laying the groundwork for creating the alien that can conjure new proteins (if you will). i’ll hand it to him for the intro, because it’s his to tell:
Biology is interconnected. Small molecules alone aren’t enough on their own, genomics aren’t enough, proteomics aren’t enough — it’s the interplay between them, the pathways, that govern a system. Take you — or more precisely, your liver, your gut, your brain, and the traffic between them. To model that, we have to stop treating each omics layer as its own island and start drawing the connections between them. A multi-omics embedding space is one way to make that tractable: genes, proteins, and small molecules all in one space, functionally related things sitting near each other, directions that mean something biological. That’s what I built here.
The embedding space was never the goal — it’s the groundwork. You can’t search for a new pathway in a space that doesn’t exist yet, and there was nothing there to build on, so the space came first. It’s part of building a model that can learn from experimental data, pick up on interactions, and propose new pathways — or alien proteins, if you will. Think of building the space as mapping the terrain before you drill: you chart what’s there before you go looking for what isn’t.
So instead of giving each kind of biological entity its own representation in its own database — genes here, proteins there, small molecules somewhere else, with no native way to cross-reference — the model learns one shared space where all of them live together from the start. Directions in that space carry biological meaning: gene-encodes-protein, protein-catalyzes-reaction. Geometry becomes a stand-in for biology.
so what does one shared space actually let you do?
Start with finding pathways. Think of it like drawing a road map of a place you can’t see, but your instruments can sense. You watch the traffic — that’s expression — and you block intersections — that’s perturbation. Block enough of them, watch how the traffic reroutes, and you slowly work out where the roads lead, which detours exist, where a new road might relieve congestion. That’s what we’re doing when we knock out a gene and watch expression change. Do it enough times and you can train a model that turns those changes into hypotheses for pathways — or generates new, plausible pathways consistent with everything it’s seen.
that “generate a plausible thing that isn’t in the data” move is the part i keep turning over. let me take a detour. my friend andre was building a social-media browser that lets you direct your feed instead of being directed by it. part of it was a genuinely good recommender: you tell the system what you want to see, it generates a synthetic, ideal post — exactly the thing you’d want — embeds it, then hands back the real posts sitting closest to that synthetic point.
now translate that into an everything-in-bio-embedding space. instead of a synthetic ideal post, you generate a synthetic ideal protein, or pathway — a point that, if it existed, would explain the disease or unlock the function. then you look at which real proteins, genes, and pathways sit closest. those are your candidates: diagnostics, targets, interventions, or starting points for editing existing structures through gene or protein design.
that synthetic point doesn’t have to have a close real neighbor. if the nearest real thing sits far away, the model is pointing at something biology hasn’t made yet — a pathway, or a protein, that’s plausible given everything it’s seen but doesn’t exist. an alien protein. buildable, in principle, once you know the edits. note that the model won’t only generate feasible proteins – you’ll have to filter and experiment.
that’s the dream. the catch is whether we can embed enough of biology to make it real. can we embed everything — not just molecules and below, but cells, organs, disease symptoms, even species? maybe. but there’s a lot in the way.
The dimension we’re missing right now is location. Locality lives implicitly in expression and co-expression data, which works inside a single tissue but starts to break when you model cross-organ things like the gut-brain axis. The architecture can extend — you can duplicate nodes per tissue and model their interactions — but the systemic, cross-tissue co-expression data you’d need to train that is much rarer than tissue-specific data.
Miao Guo, Lennart’s PI, goes a layer further upstream: even within a single omics type, data from different platforms often can’t be harmonized cleanly — sometimes not at all.
the blocker, in other words, is clean and abundant data. not architecture, not even compute. a classic conundrum — but a solvable one. it’s a question of standards. standardization is a known blocker for a more reproducible, reusable scientific record, and efforts like briefly.bio are already tackling it from the lab-protocol side, ushering in the era of autonomous labs.
now, say we get the data. embeddings are an ai-first architecture, and i, for one, can’t read it — none of us speak vector. the nice thing is that the synthetic node decodes: it translates back into language i can actually understand and act on. take fatty liver, which Lennart is running the model on now at King’s: it surfaces a candidate pathway or protein that would drive the disease, you decode it, and out comes a diagnostic candidate or a drug target in plain language. [preprint in preparation]
so what you’ve got is the outline of an autonomous hypothesis generator grounded in the actual topology of biology — real pathways, real genes, real proteins, cells, organisms — reaching toward the ones that aren’t real yet. we can’t wait to see where it goes.
one thing nags. a record like this represents knowledge for machines increasingly doing the reasoning over it, not for humans — which is either thrilling or icky depending on who you ask2, and a question i’ll take up in its own post. for now i’ll just plant a flag: even an ai-first record needs a human-readable layer on top — hypotheses, designs, datasets, protocols — all anchored in these embeddings. i have a lot of thoughts on that. but that’s for next time.
this is for anyone who wants AI to make science better — better measurement, better collaboration, better odds of actually discovering something. if that’s you, and you’ve got thoughts on any of this, or you’re building in the same direction, get in touch.
ABOUT THE AUTHORS
Lennart Otte is a PhD researcher in the Department of Engineering at King’s College London, in Miao Guo’s group. he studied Computer Science at King’s before a master’s in Biomedical Engineering (Neurotechnology) at Imperial College London, where he worked on modelling the brain’s chemistry in response to ketamine as an antidepressant. his PhD began in systems biology and data — protein synthesis, waste-to-resource recovery — and has since shifted toward medicine and drug-interaction pathways, using machine learning over metabolic networks and gene and multi-omics databases. he’s the lead author of Multi-Omics biological embeddings for ML-models (with Christer Hogstrand, Adil Mardinoglu, and Miao Guo), the paper this post is built around. (his research is funded by the EPSRC DTP at King’s, with additional support from Unilever.)
Carla Ostmann has spent five years researching and trying to improve the infrastructure of science — how knowledge gets represented, published, and reused. next to funding great science at Positron, she’s busy with independent on scientific knowledge representation. she has Opinions about scientific publishing, some of which live in this earlier post and on the Future of Science Podcast she hosted for two years, interviewing thought leaders in metascience.
thanks to Miao Guo, Andre, Pim, Darren and Harry Rickerby for review, inspiration and feedback.
some interesting proteins and peptides that have been engineered with alien / unnatural amino acids already. semaglutide (ozempic) is one example - it has an unnatural 2-aminoisobutyric acid in place of alanine which makes its half life much longer. a few different companies that have been started to incorporate unnatural amino acids and nucleic acids - Synthorx (X and Y base pairs), Ambrx, and Unnatural Products.
thanks to Darren for pointing this out to me.
Tangent: What’s AI, really?
this question came up during editing this post:
The question isn’t really “are you using AI for discovery.” the line where statistics ends and AI begins isn’t well defined — every intro course starts with linear and logistic regression, and nobody calls that AI; everyone calls an LLM AI; the middle is fuzzy. The question is what you use it for. Extracting structure from a large, clean, specialized dataset? That’s where it’s valid, and that’s what we do. making decisions for you, writing code you never look at again1a, giving medical advice from a model that can hallucinate? I’m much more skeptical.
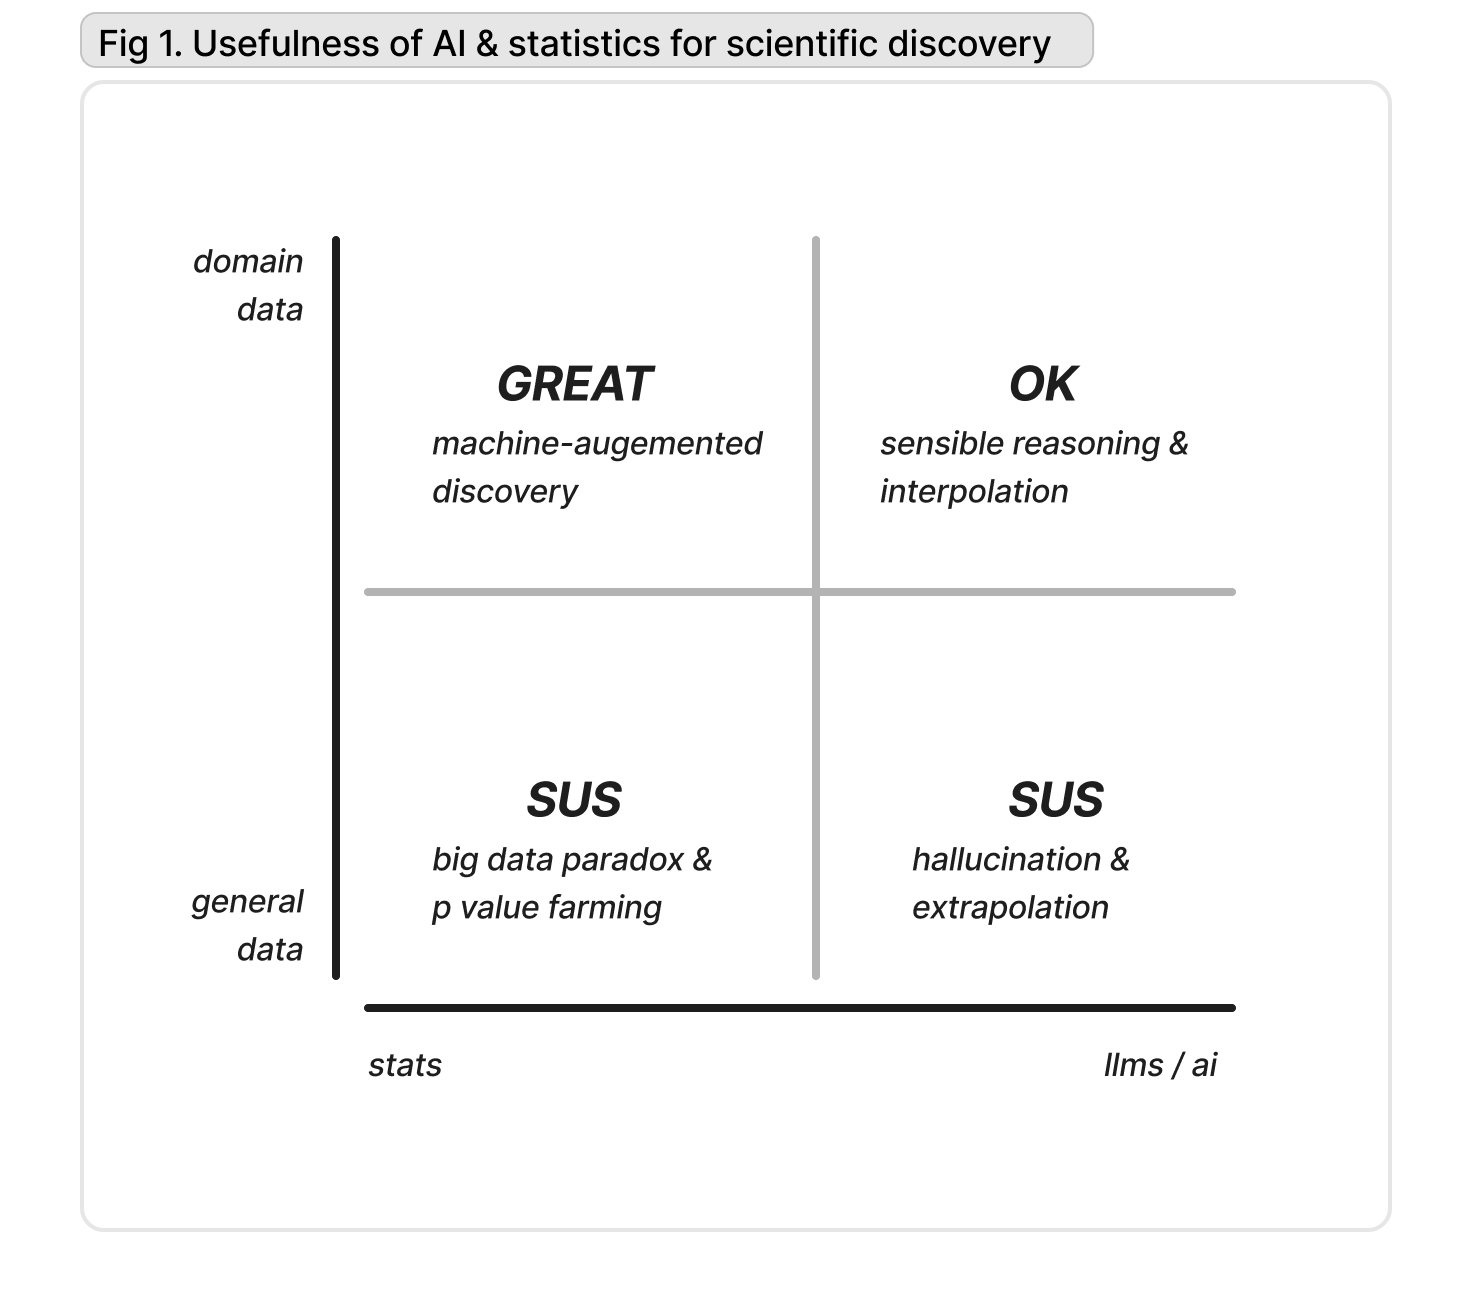
It also depends enormously on the data. Our model is specialized on pathways and biological Datasets, so when we train it to draw conclusions there, I trust it more. ask a general model “i have these symptoms, what should i do” and it’ll answer — but it wasn’t built for that. and there’s a deeper limit: these systems are very good at interpolation — smoothing, adapting something they’ve already learned, rephrasing — and not good at extrapolation: working out genuinely new concepts, or reasoning a chain of logical conclusions across hundreds of sources. There’s a study where a model trained on planetary orbits predicts them beautifully but never recovers Newton’s law of gravity underneath; even frontier models fail the same test. logical leaps over complex material are still the missing piece.
1a this had me laughing. unreviewed coding is all i use it for